
Large language models change how companies handle data processing. Every business wants to deploy smart AI tools quickly.
However, building massive infrastructure presents serious technical hurdles daily. Engineering teams struggle to keep servers running without crashing.
Managing immense computational power requires specialized hardware and smart layouts. Without proper planning, energy bills can bankrupt a growing startup.
Let us explore how engineers scale these massive systems safely. Smart infrastructure choices save companies millions in wasted cloud costs.
Overcoming Hardware Bottlenecks in GPU Clusters
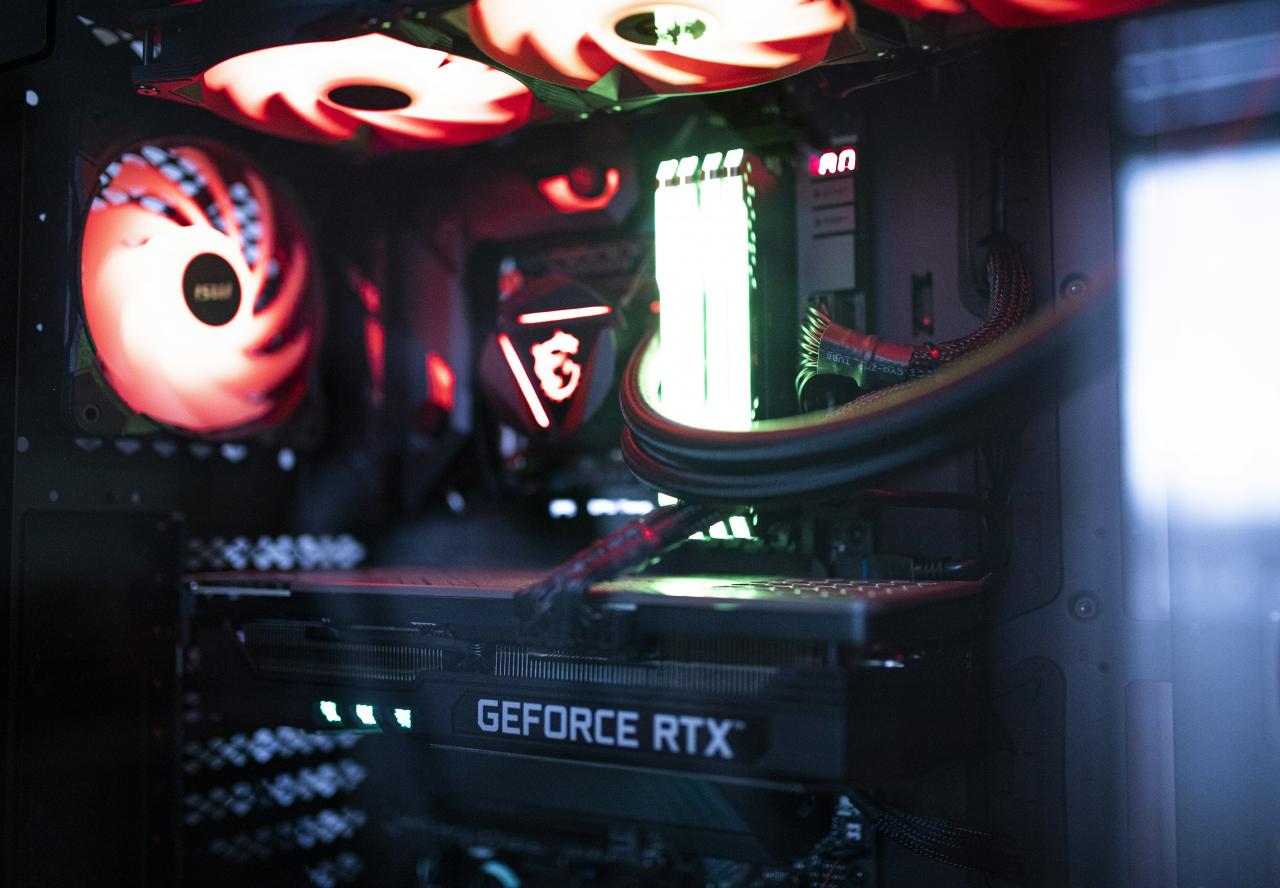
Training massive models demands thousands of high-end graphics cards. Communication lag between processors often slows down the entire system.
Engineers must optimize network topology to maximize data transfer speeds. Using high-speed interconnects prevents costly processing bottlenecks during training phases.
Many teams buy expensive hardware without optimizing software layers first. Proper driver configuration often unlocks hidden performance boosts instantly.
- A. High speed interconnects reduce latency between heavy processor clusters.
- B. Proper driver tuning maximizes raw hardware computing efficiency daily.
- C. Strategic cluster placement prevents catastrophic network bandwidth failures.
Balancing workloads across multiple nodes requires advanced orchestration software. Kubernetes helps teams manage distributed training jobs without losing their minds.
Hardware failures happen frequently when pushing components to their limits. Automated failover systems ensure your training runs resume without manual intervention.
From my professional viewpoint, neglecting thermal management destroys expensive GPUs prematurely. Investing in superior liquid cooling systems saves your hardware from melting down.
Optimizing Memory Management for Massive Datasets
Large language models consume staggering amounts of RAM during execution. Running out of memory causes training jobs to crash instantly.
Developers use techniques like gradient checkpointing to save precious space. Sharding model weights across multiple devices distributes the heavy memory load.
Ignoring memory optimization leads to bloated containers and slow response times. Smart caching strategies keep your inference pipelines running smoothly and fast.
- A. Gradient checkpointing reduces memory footprints during heavy training cycles.
- B. Weight sharding distributes massive model parameters across multiple servers.
- C. Smart caching mechanisms speed up real time user inference queries.
Dynamic batching allows servers to process multiple user requests efficiently. This approach maximizes GPU utilization while keeping operational costs low.
Memory leaks can silently kill your production servers overnight. Setting up automated memory profilers helps your team catch leaks early.
As a tech writer, I see many startups waste budget on oversized servers. Fine-tuning memory allocation parameters always beats throwing expensive hardware at problems.
Managing Cloud Costs During High Scale Training
Cloud computing bills can spiral out of control within days. Running massive clusters requires strict budget monitoring and smart resource allocation.
Spot instances offer cheaper computing power for fault-tolerant training jobs. However, sudden interruptions require robust checkpointing systems to save progress.
Many engineering managers forget to shut down idle development servers. Automated scripts can turn off unused instances outside of working hours.
- A. Spot instances cut cloud computing expenses by utilizing spare capacity.
- B. Automated shutdown scripts prevent wasted spending on idle servers.
- C. Resource tagging helps finance teams track exact project expenditures.
Hybrid cloud architectures let companies balance private servers with public giants. This flexibility protects sensitive corporate data while scaling compute power infinitely.
Negotiating enterprise discounts with cloud providers lowers long-term operational overhead. Every saved dollar increases your company runway and profit margins.
I strongly believe that financial literacy is crucial for modern engineers. Writing cost-efficient code protects your startup from unexpected financial disaster.
Ensuring Low Latency for Real Time Inference
Users expect instant responses when interacting with AI applications. High latency frustrates customers and destroys product adoption rates quickly.
Model quantization shrinks file sizes without losing core intelligence. Smaller models load faster and execute inference queries with minimal delay.
Distributing edge servers closer to your user base reduces network travel time. Content delivery networks help route API requests to the nearest data center.
- A. Model quantization compresses file sizes for faster execution speeds.
- B. Edge deployment brings processing power closer to end users.
- C. Request load balancing prevents single servers from choking up.
Asynchronous processing handles background tasks without blocking user interactions. This seamless design keeps your application interface snappy and responsive.
Monitoring round-trip times helps engineers spot slow network routes immediately. Continuous profiling ensures your production environment maintains lightning-fast performance.
From my perspective, user patience has dropped to absolute zero today. Speed is not a luxury feature; it is a fundamental requirement for survival.
Building Resilient Failover Systems for AI Pipelines
Production systems inevitably face unexpected outages and software bugs. Designing for failure ensures your AI application stays online 24/7.
Redundant server clusters take over instantly if primary nodes crash. Automated health checks monitor system vitals without requiring human oversight.
Data backups must run continuously to prevent catastrophic information loss. Testing your disaster recovery plan regularly guarantees it works when needed.
- A. Redundant node clusters provide instant backup during server crashes.
- B. Continuous data backups protect valuable corporate information from loss.
- C. Automated health checks spot failing components before disasters happen.
Graceful degradation keeps basic features working even during major outages. Users prefer a slightly slower app over a completely broken screen.
Post-incident reviews help engineering teams learn from past system mistakes. Documenting root causes prevents the exact same bug from happening twice.
I always tell teams that hope is never a valid engineering strategy. Building bulletproof failover mechanisms separates amateur projects from enterprise giants.
Scaling Data Pipelines for Continuous Model Updates
AI models require fresh data to stay relevant and accurate. Building scalable ingestion pipelines keeps your training loops fed constantly.
Streaming data architectures process millions of user inputs in real time. Cleaning incoming data at the source prevents garbage from entering models.
Storage scalability matters just as much as raw computing power. Distributed file systems handle petabytes of text without slowing down operations.
- A. Streaming architectures handle millions of incoming data points effortlessly.
- B. Automated data cleaning prevents toxic inputs from corrupting models.
- C. Distributed file storage accommodates endless petabytes of training text.
Version control for datasets ensures reproducibility during future training runs. Tracking data lineage helps engineers trace the exact origin of model errors.
Collaborative data labeling tools speed up supervised fine-tuning workflows significantly. Empowering human reviewers ensures high-quality training datasets every single time.
As a content creator, I see data quality as the ultimate competitive edge. Clean data pipelines guarantee that your scaled infrastructure delivers true business value.
Conclusion
Scaling large language models requires discipline and smart architectural choices. Every hardware upgrade must align with your actual business goals.
Monitoring cloud costs keeps your startup financially healthy and stable. Low latency inference guarantees your users stay happy and engaged daily.
Resilient failover systems protect your applications from unexpected catastrophic crashes. Clean data pipelines ensure your models learn from quality information.
Start applying these proven infrastructure strategies to your projects today. Your engineering team will build faster and more reliable systems.
Continuous learning helps technical teams adapt to rapid industry changes. Never stop optimizing your code for maximum performance and efficiency.
True digital scaling comes from balancing hardware power with smart software. Your proactive infrastructure planning today guarantees massive market success tomorrow.
Let us commit to building resilient and scalable artificial intelligence. The future of technology depends entirely on our engineering discipline.

